Scrape any web page for your AI agents

No reviews yet, be the first!
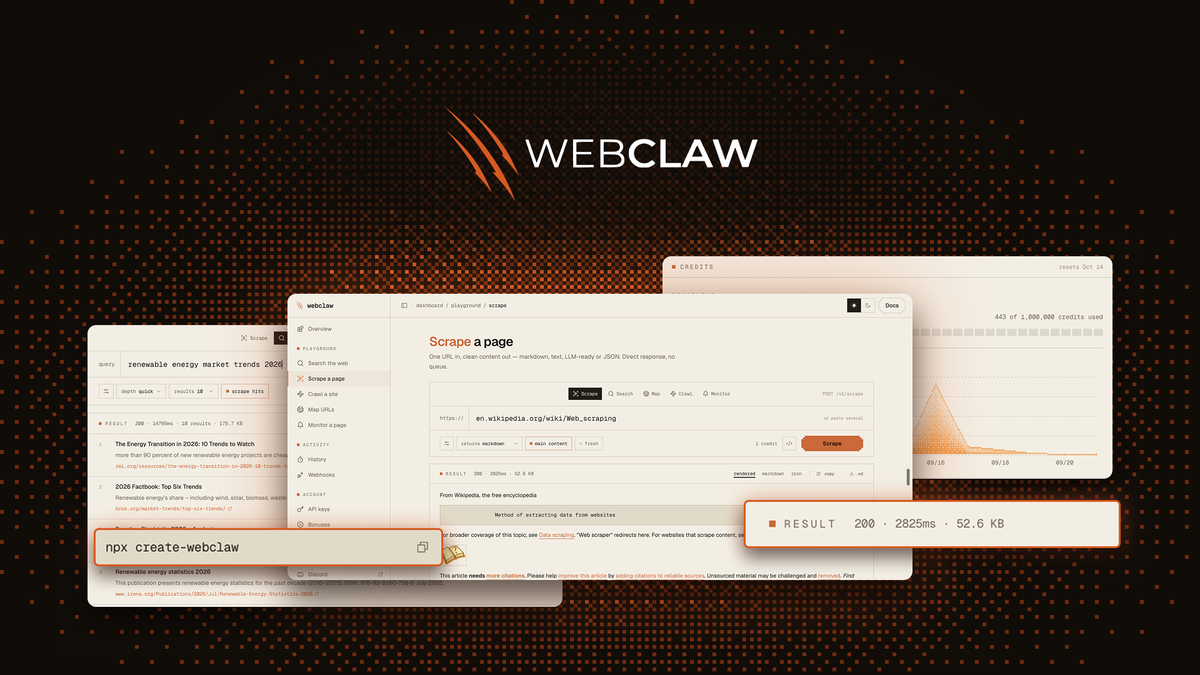
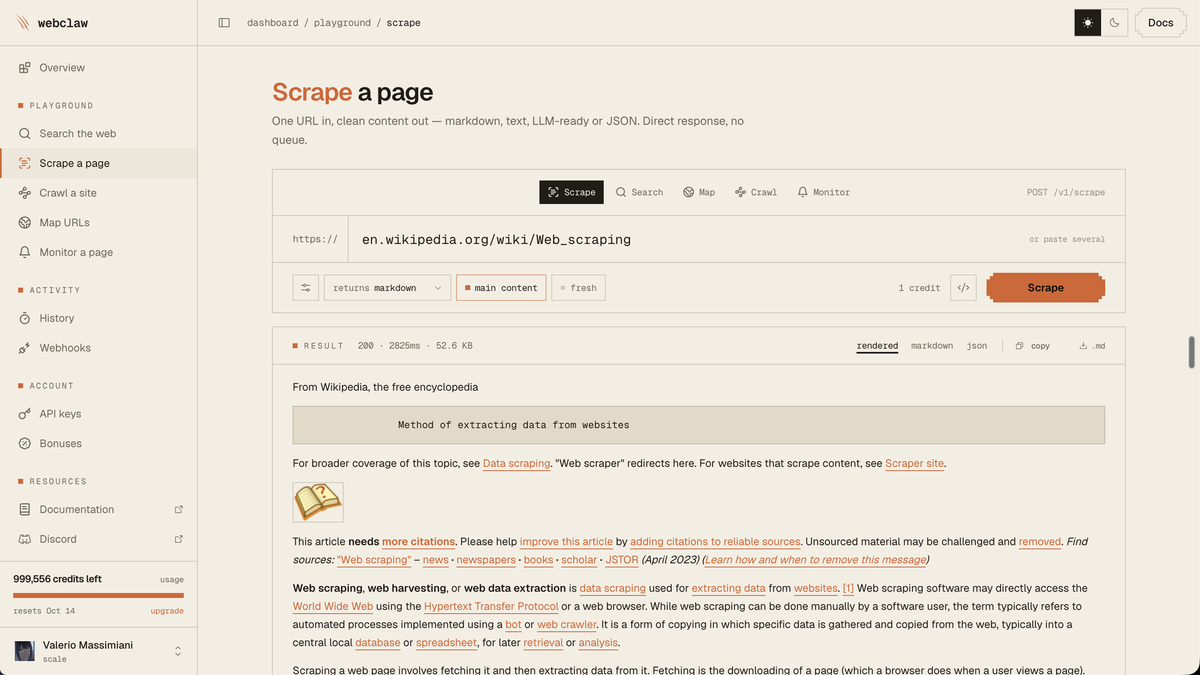
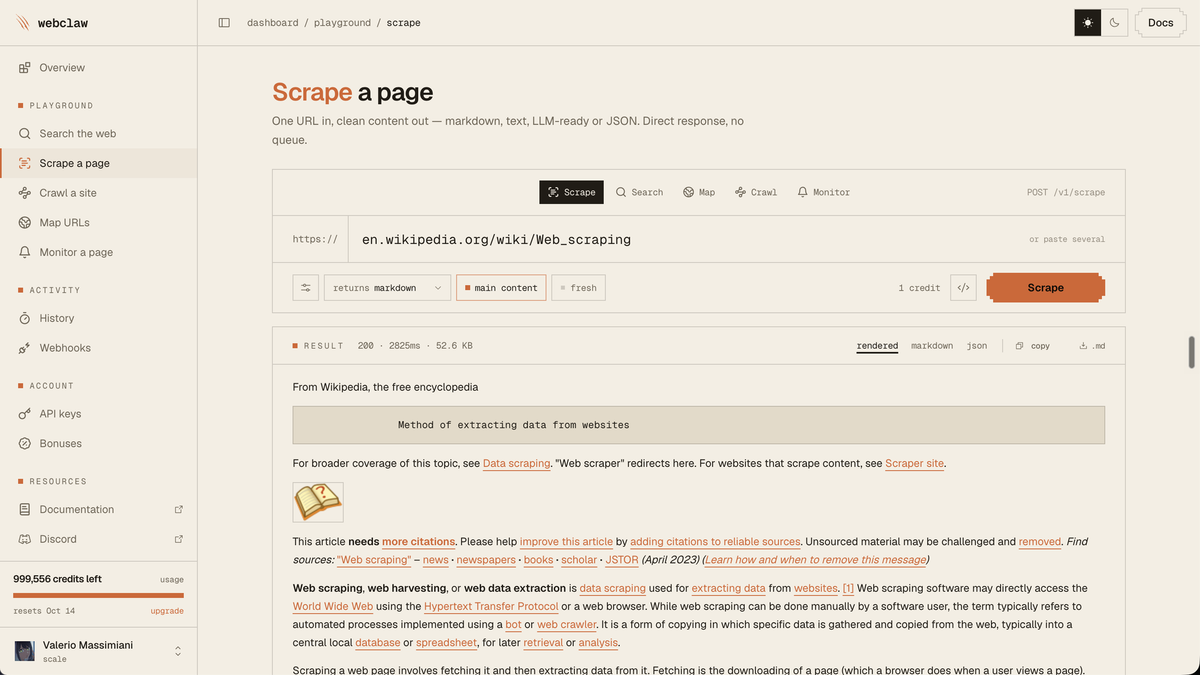
Webclaw playground scraping a Wikipedia page and returning clean Markdown, with the response shown at 200 OK in 2.8 seconds for one credit.
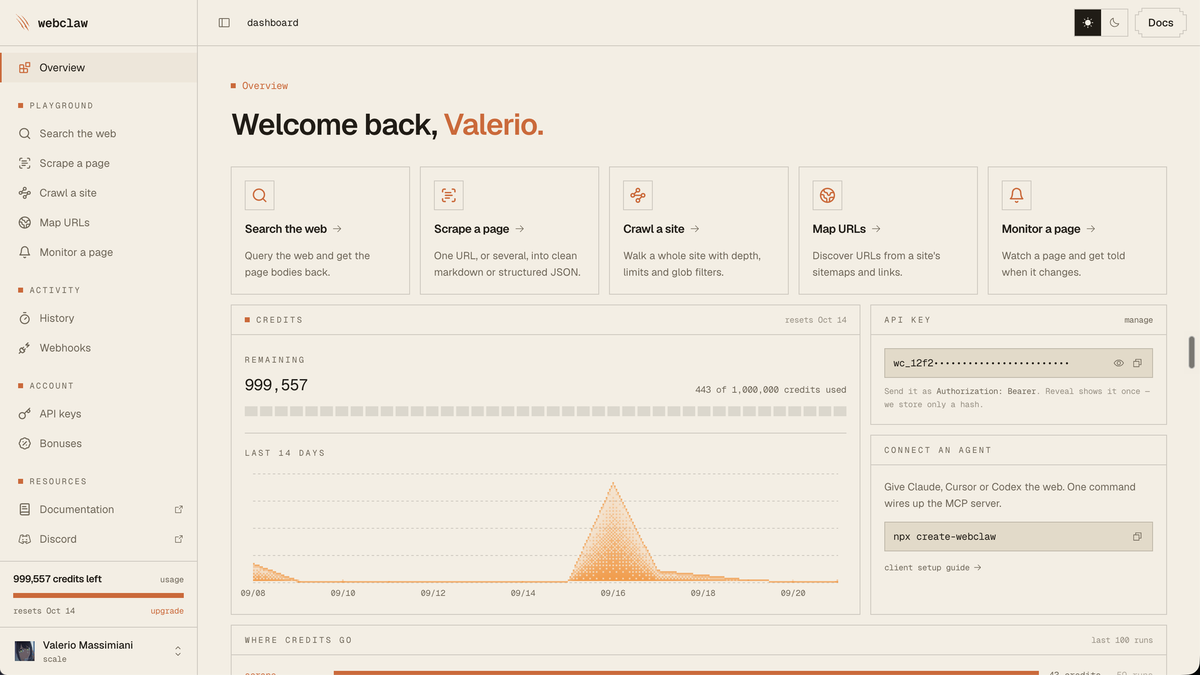
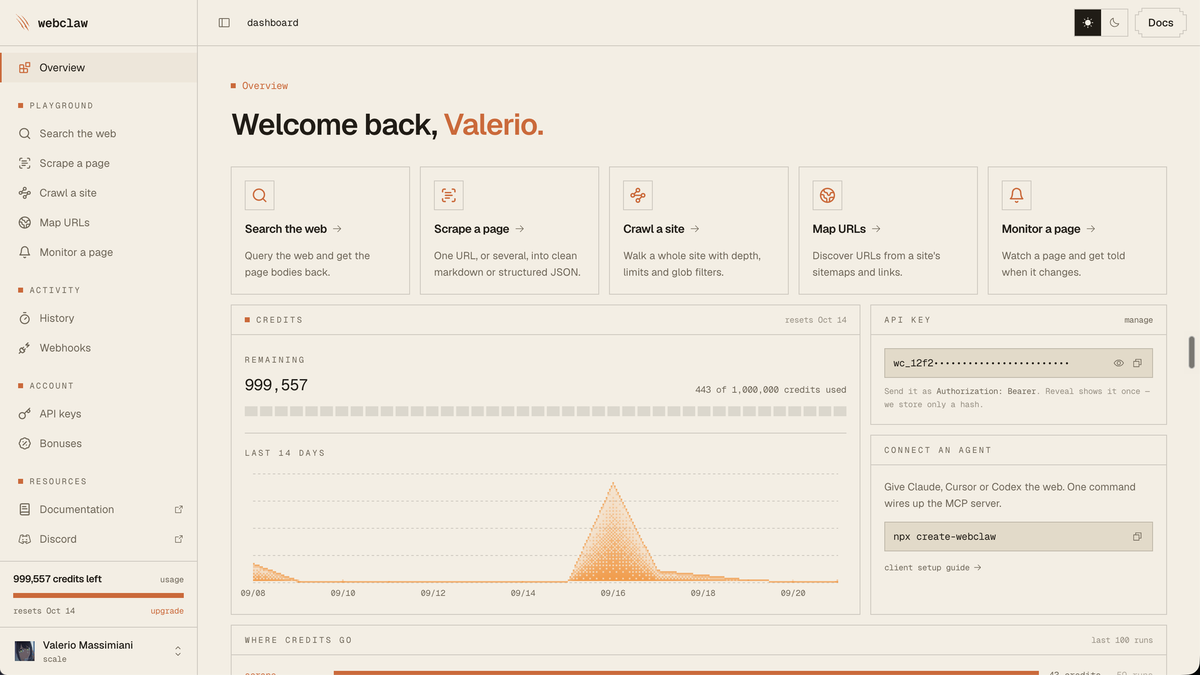
Webclaw dashboard showing 999,557 API credits remaining, a 14-day usage chart, an API key panel and one-command MCP agent setup.
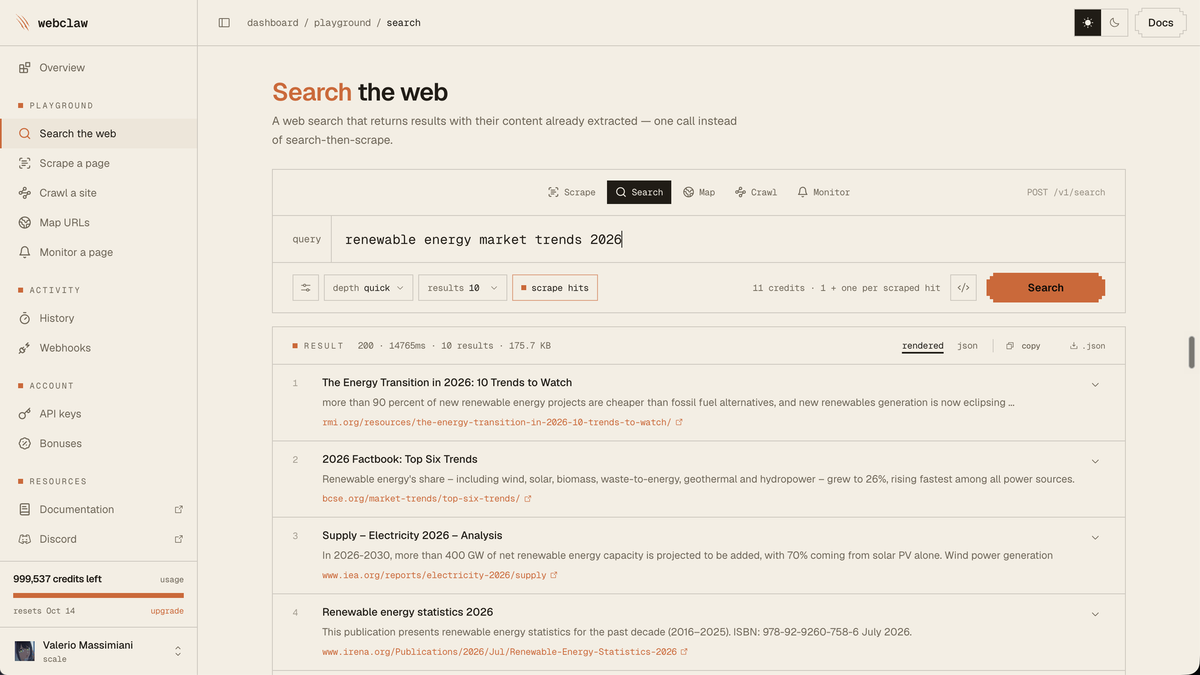
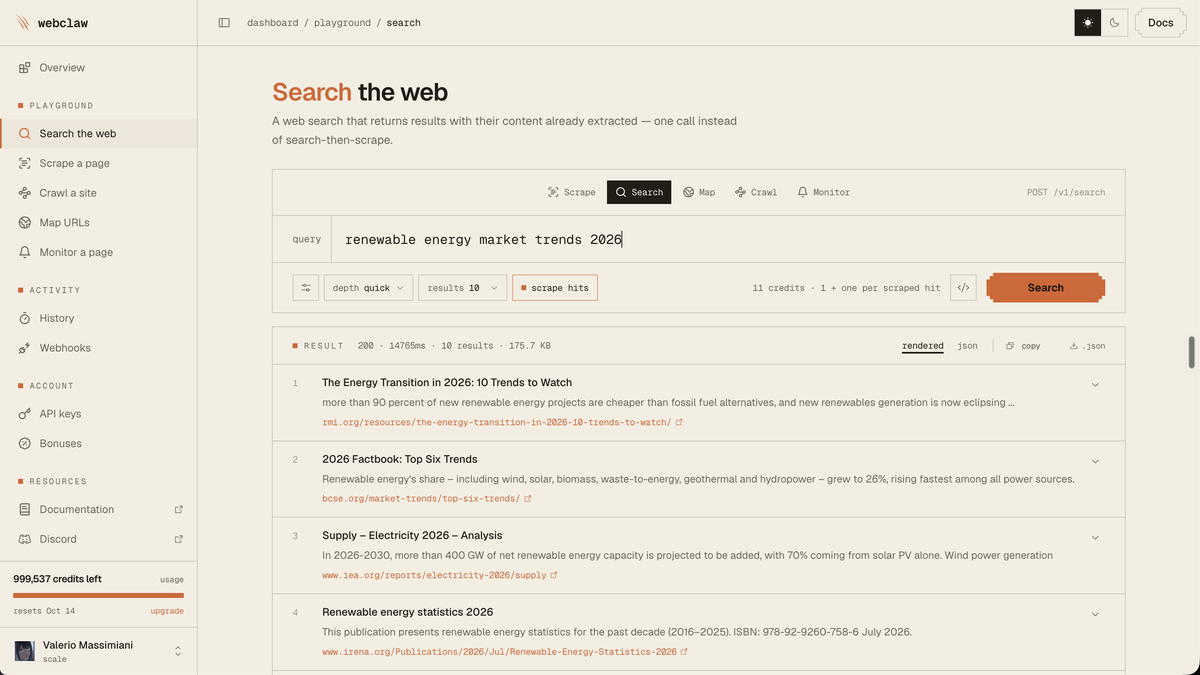
Webclaw web search API returning ten results with page content already extracted, in a single call taking 175.7 KB and 200 OK.
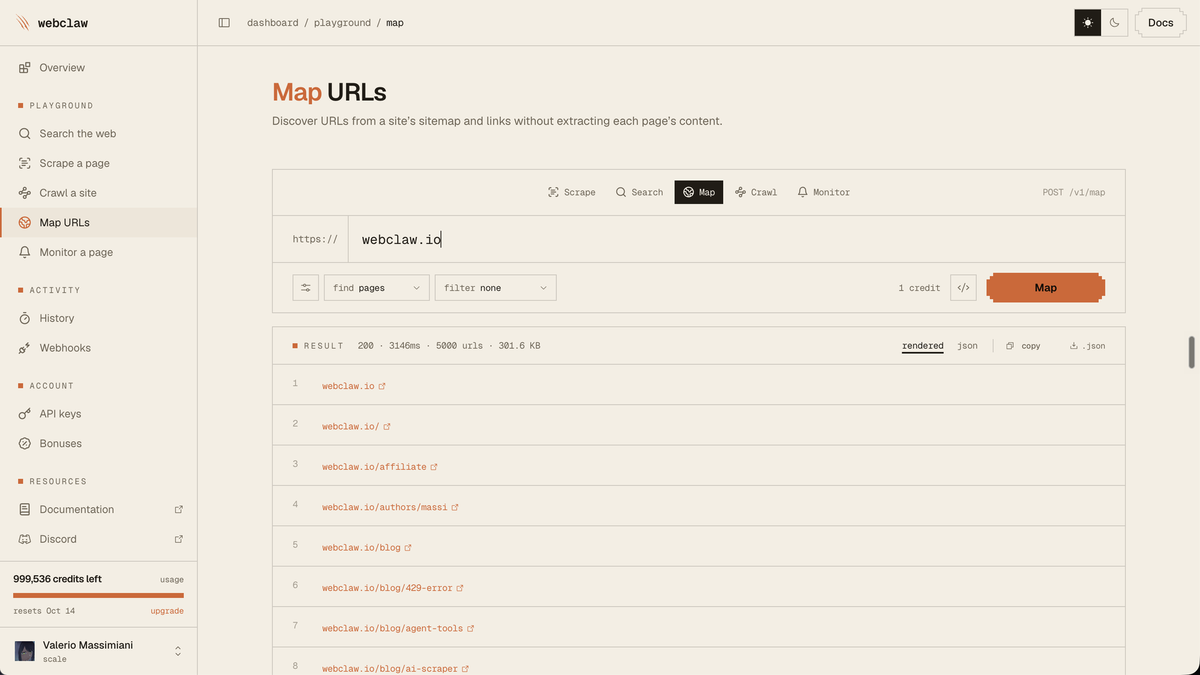
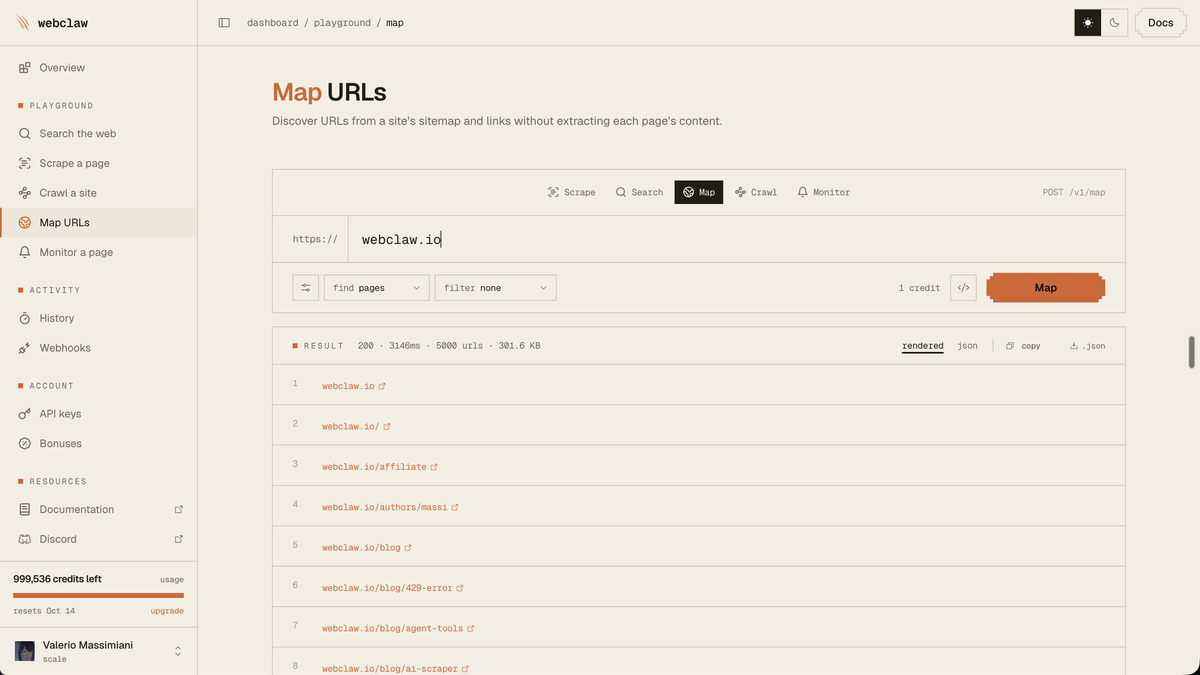
Webclaw mapping a website's sitemap, discovering 5,000 URLs in 3.1 seconds without extracting each page's content.

Webclaw

Plus access ends in
00
Hours
:
 
00
Mins
:
 
00
Secs
-84%$49
$299
  • Lifetime access
  • Refundable up to 60 days
  • Covered by our We Got Your Back guarantee
AppSumo Plus

Available exclusively to AppSumo Plus members

Most scraping APIs charge extra for JavaScript, blocked sites, and AI extraction, so your bill grows with every tricky page. Webclaw turns any page into clean Markdown or JSON for one credit, no add-ons.

TL;DR

  • checkmarkTurn any public web page into clean Markdown or structured JSON your AI can actually read
  • checkmarkPay one credit for every page, including JavaScript rendering, protected sites, and AI extraction

At-a-glance

webclaw.io

Alternative to

Browse AI, PhantomBuster

Integrations

Claude, MCP, Cursor, Codex

Best for

Developers, Researchers, AI agencies

Plus access ends in
00
:
00
:
00
Webclaw logo

Webclaw

Search, map, and crawl the web with JS rendering, anti-bot solving, and LLM extraction built in

Turn messy web pages into AI-ready data

  • Paste a URL and get the page back as clean Markdown or structured JSON, with navigation, cookie banners, and sidebars already stripped out
  • Pick from six output formats, including Markdown, JSON, HTML, plain text, LLM-optimized, and raw
  • Run LLM extract, summarize, diff, and brand tools on any page you scrape
  • Read it back in one response with no queue to poll and no job ID to chase
Turn messy web pages into AI-ready data

Know exactly what every page will cost

  • Pay one credit per page, with JavaScript rendering, anti-bot solving, and AI extraction into your own JSON schema included
  • Keep your allowance whole with no rendering, protected-site, or AI surcharges waiting at the end of the month
  • Watch the meter, not the invoice with usage broken down by endpoint, so you can see where your credits go
  • Switch from Firecrawl without rewriting your code using the /v2 drop-in compatibility layer
Know exactly what every page will cost

Get search results with the pages attached

  • Skip the second round trip since results arrive with their content already extracted, not just a list of links to fetch
  • Feed an agent directly with clean text per result instead of ten URLs it has to crawl itself
  • Control your spend by choosing how many results get scraped, so a broad query never turns into a surprise bill
  • Connect Claude, Cursor, Codex, or Windsurf through the MCP server, or build with the REST API and CLI tool
Get search results with the pages attached

Map a whole site before you crawl

  • Map thousands of URLs in seconds from sitemaps and links, without extracting a single page
  • Plan the crawl first so you scrape the 200 pages you want instead of the 5,000 you don’t
  • Filter before you fetch with glob patterns, then send only the matching URLs to scrape or crawl
Map a whole site before you crawl

Choose the plan that’s right for you

Feel secure in your purchase with AppSumo's 60 day money-back guarantee.

Refundable up to 60 days
Covered by our
We Got Your Back guarantee
Deal terms & conditions
Webclaw
See Webclaw
Founded April 1, 2026
🇮🇹Rome, Italy
1-10
Startup
Bootstrapped

I spent years getting pages that did not want to be read

Before any of this was about AI, I was building monitors. Dozens of them, watching ticket and retail pages across a handful of countries, checking whether something had come back in stock. The parsing was never the hard part. The hard part was getting the page at all. Half my week went on fingerprints, headers, proxies and the particular way each site decided I was not a person. I have a folder full of repos whose names are just a site and the word monitor, and most of them exist because the previous approach stopped working on a Tuesday.

Then the models arrived and the thing on the other end changed. A monitor wants one row: is it in stock, yes or no. An agent wants the whole page, in text it can actually read. Same fight to get in, completely different thing to hand back when you do.

So I looked at what was on sale and the pricing made no sense to me. Plain page, one credit. Needs JavaScript, more. Site blocks you, more again. Want structured JSON instead of a wall of text, four or five times the base price. Those three things were exactly what I had spent years doing, and they were being sold as extras. They are not extras. For an agent they are the normal case, on almost every page it touches.

I already had the hard half working. So I built the other half and priced it the way it should have been priced. Webclaw charges one credit per page. Rendering, blocked pages, AI extraction into your own schema, all of it, one credit. Not a launch promotion, it is how the biller is written.

I write the code and I run the servers. If something breaks you are not filing a ticket into a queue, you are emailing the person who broke it.

Questions & reviews